

Multimodal Datasets for Text, Image, Audio, and Video AI
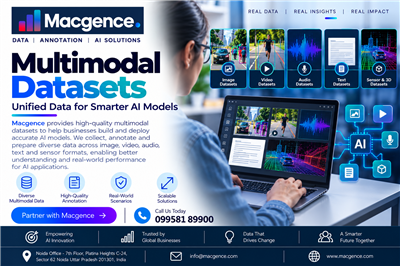
Multimodal datasets help AI systems understand information from different sources, including text, images, audio, and video. They allow models to connect written words with visual details, spoken language, and real-world actions. For example, an AI system can use these datasets to describe images, understand speech, summarize videos, or answer questions about visual content. Good data quality and accurate labeling are important for training models to recognize patterns and produce useful results. Creating multimodal datasets requires careful data collection, consistent annotation, and proper organization so that different types of information work together. Macgence supports AI data preparation by focusing on structured and well-organized training data. With suitable examples across multiple formats, datasets can help developers build AI applications that understand context and handle more complex tasks. Visit now: https://macgence.com/blog/multimodal-datasets-the-complete-guide-to-ai-training-data-for-modern-ai-models/
